FIELD NOTES / SHAHARIER SHOUROV
Building an Automated SQL ETL Pipeline
Preparing bank transaction data with PostgreSQL and scheduling a workflow with pgAgent.
Published · Updated
From a transformation to a workflow
This project uses PostgreSQL to prepare a bank transaction dataset containing more than 116,000 records. I wanted to bring the cleaning, deduplication and audit steps into a workflow that could be scheduled with pgAgent.
The project cover in this portfolio records 116,201 source rows. That is a dataset size, not a throughput benchmark or a claim about the volume of a live production service.
Preparing the data
The project notes describe account identifiers represented in scientific notation, inconsistent currency formatting and mixed date formats. These are different problems and need different checks.
In particular, an identifier should not be treated as a number simply because it contains digits. If precision has already been lost upstream, changing its display format cannot restore the missing digits. The raw source remains essential for reconciliation.
Keeping runs traceable
The workflow includes deduplication and audit logging. A useful log should explain when a run happened, whether it completed and what happened to its records. A successful query alone does not tell the whole story.
Repeatability and recovery need to be demonstrated through the implementation and execution logs. Describing a scheduled workflow is not enough to establish how it behaves when input is repeated or a step fails.
Scheduling with pgAgent
pgAgent is a separate scheduling agent used with PostgreSQL. Scheduling a job also depends on the agent, database and permissions being available. A schedule alone does not establish continuous operation or eliminate the need to monitor a workflow.
Read the case study for the workflow overview and the evidence still needed to demonstrate operational reliability.
Related field notes
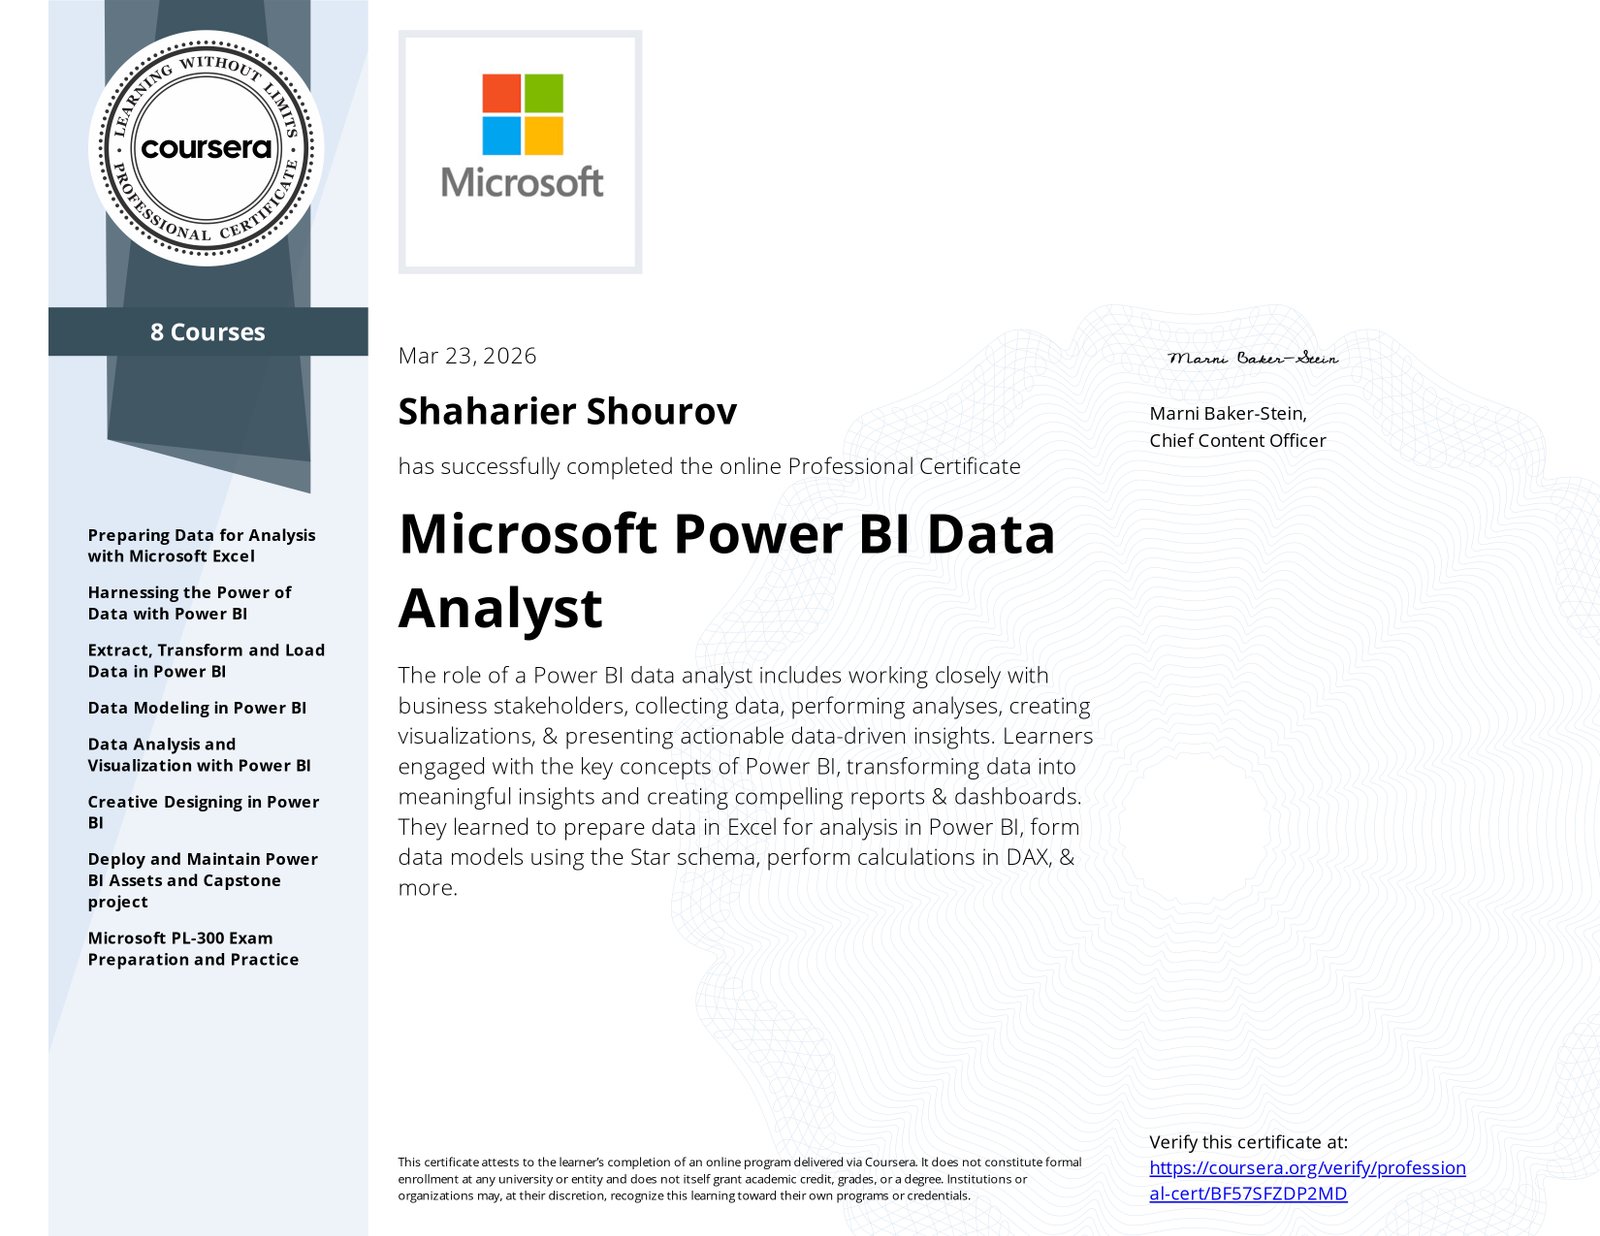
Earned the Microsoft Power BI Data Analyst Professional Certificate
Completing Microsoft's eight course Power BI Professional Certificate on Coursera.
Read article ↗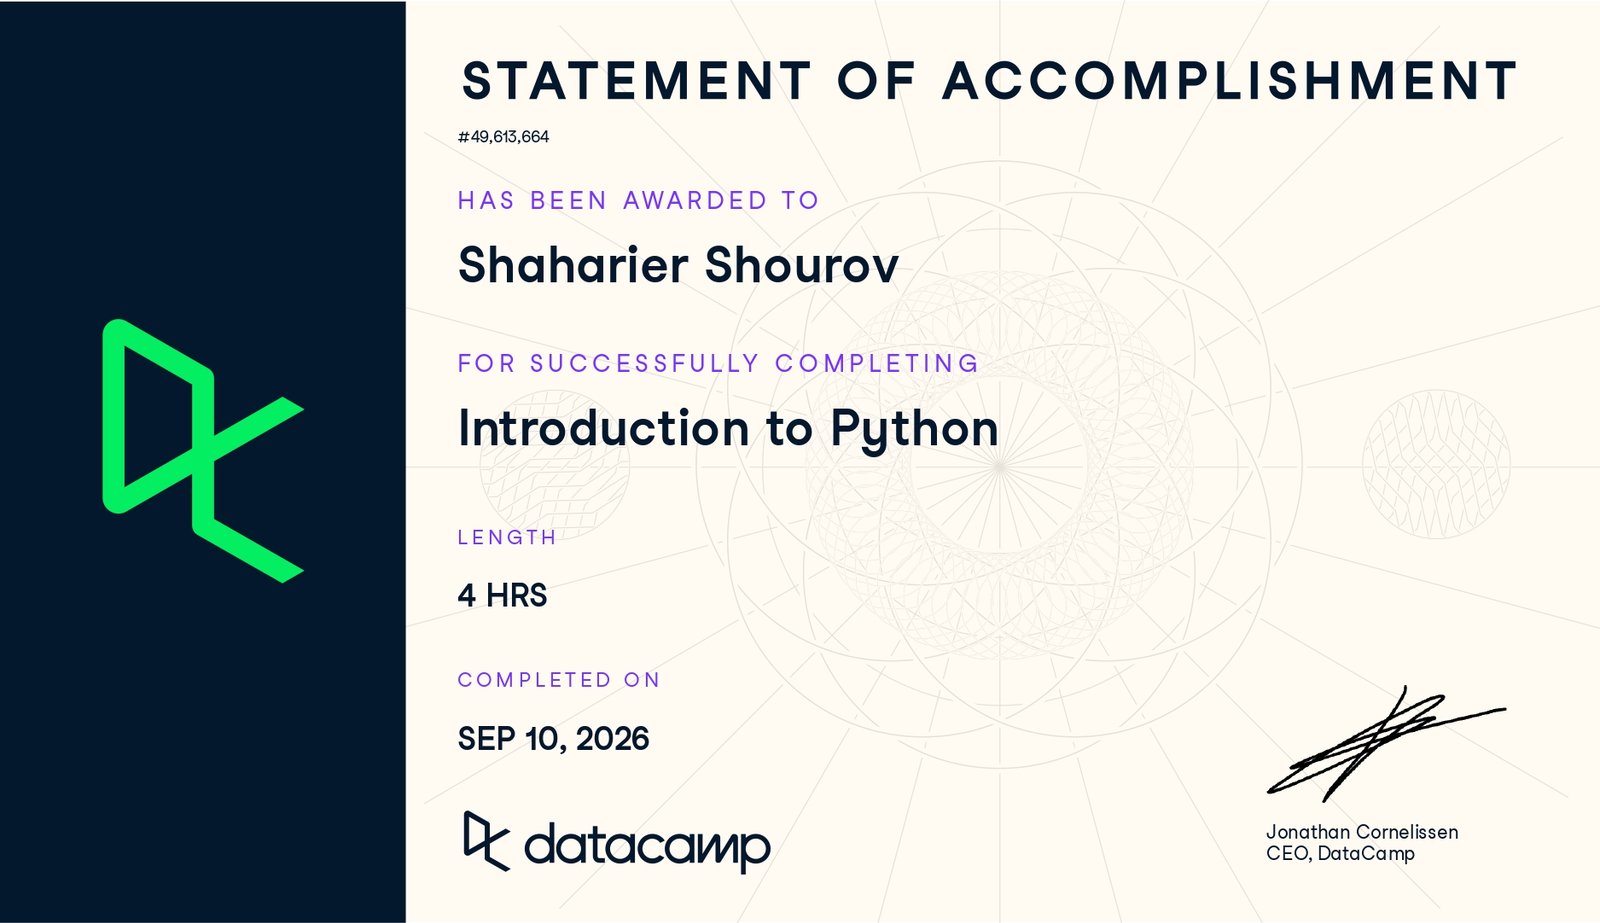
Back to Learning: Starting Data Engineer in Python
Building on SQL while learning data engineering with Python.
Read article ↗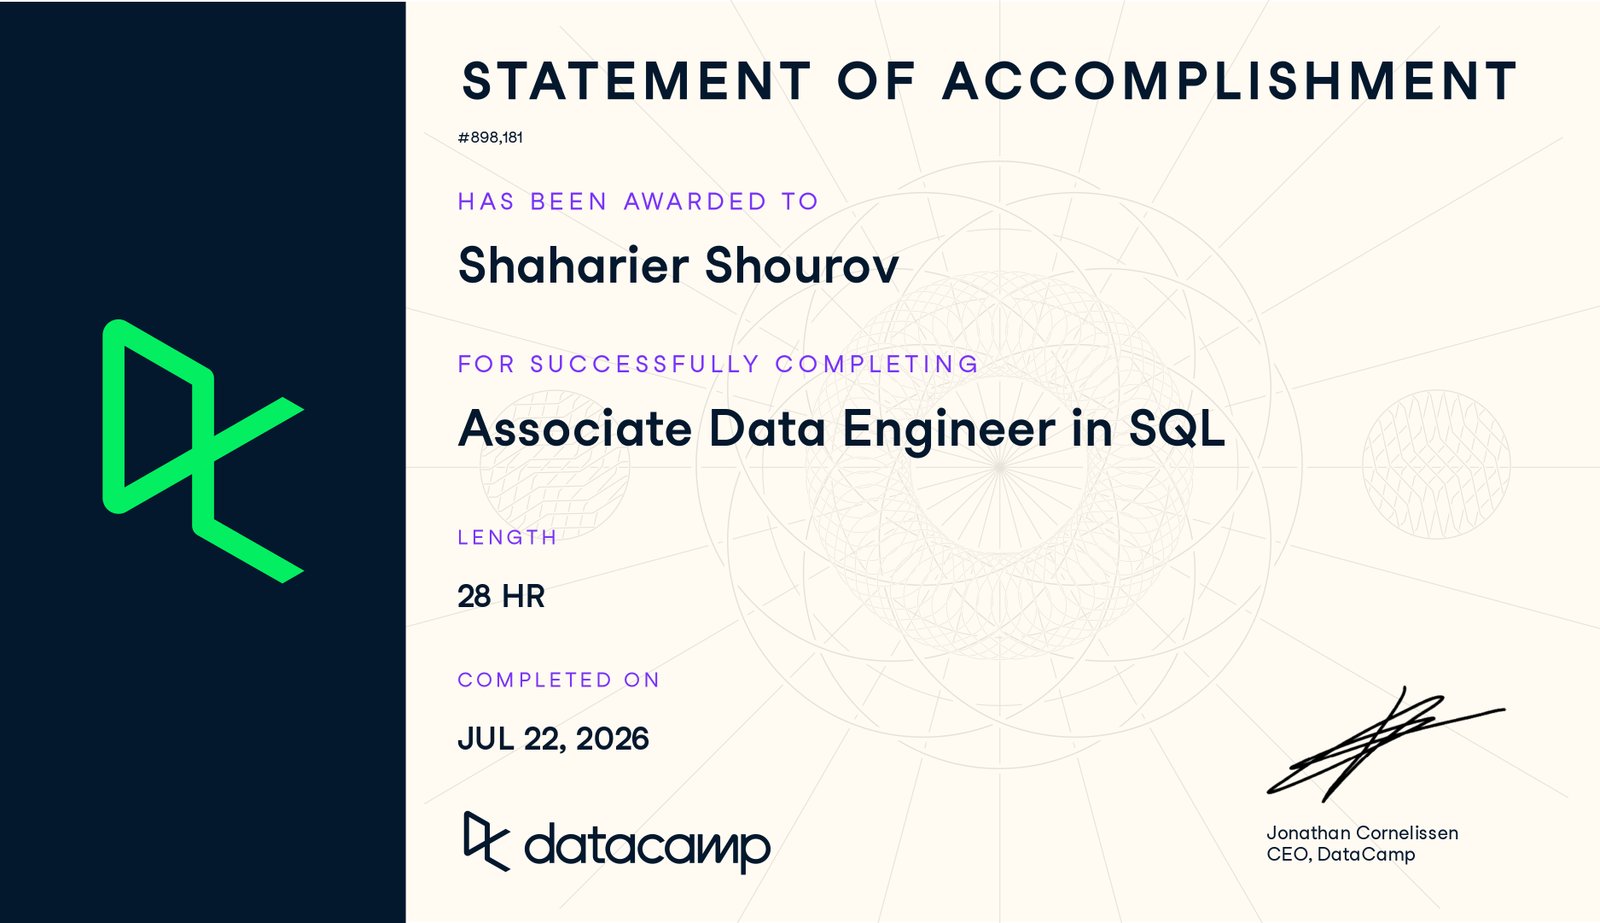
Completed Associate Data Engineer in SQL
Developing my foundation in SQL, database design and data warehousing.
Read article ↗